
03. Visualizing Computational Pipeline Dependencies
Source:vignettes/compute_graph.Rmd
compute_graph.RmdWhy track a pipeline as a graph
A multi-report analysis pipeline is a dependency graph whether or not anyone draws it:
raw data feeds an EDA report,
an EDA report feeds downstream computations
imputed data feeds a dozen downstream reports
Once that graph exists only in the analyst’s head, two things get hard to answer: “if I change this upstream file, what needs to be re-rendered?” and “can a new collaborator see the whole pipeline at a glance?”
compute_graph.R answers both by representing every file
in the pipeline (raw data, rendering scripts, derived artifacts) as an
S4 object with a stage, an artifact_role, and
links to what it depends on and what it produces, then building an
igraph/tidygraph graph from those links. It is
deliberately format-agnostic — a node is a path on disk, whether that
means an .R script, a .qmd report, an
.xlsx extract, or an .rds cache.
Comparison with existing R architecture (targets &
friends)
The R ecosystem has established workflow automation frameworks, most
notably targets (and
its predecessor drake), along with GNU Make wrappers and
workflowr. Understanding how
TempleCBE::compute_graph compares and contrasts with these
architectures clarifies when and why to use it.
How targets works
targets (rOpenSci, developed by Will Landau) is the gold
standard in R for function-oriented, computation-driven
pipelines. Its design philosophy centers on pure R functions
and expressions:
-
Computational units: The user defines steps via
tar_target(name, command)inside a central_targets.Rscript. -
Dependency discovery:
targetsinspects the Abstract Syntax Tree (AST) of user functions to automatically detect which targets and functions feed into others. - Caching & staleness: Cryptographic hashes of functions, expressions, and in-memory objects detect staleness. If a function’s code or input data changes, only downstream targets are invalidated.
-
Execution engine: Running
tar_make()executes the pipeline, stores serialized R objects in an internal binary cache (_targets/objects/), and skips up-to-date targets. It supports high-performance computing (HPC) clusters viacrew,clustermq, orfuture.
targets is extraordinarily powerful for long-running
statistical computations, simulation studies, and reproducible research
where intensive R calculations need to be cached and parallelized.
How TempleCBE differs
TempleCBE’s compute graph architecture is fundamentally
file-system artifact-oriented, metadata-rich, and
non-intrusive. Rather than acting as a heavy execution engine
for R expressions, it serves as a lightweight, human-interpretable
dependency auditor and visual communication layer:
-
File-system nodes vs. In-memory objects: In
targets, a target is usually an R variable or intermediate data frame stored in a private cache. InTempleCBE, every node is a tangible file on disk (FilePath), inspectable by anyone using standard file browsers or command-line tools. -
Zero-rewrite adoption vs. Functional refactoring:
Adopting
targetsdemands modularizing all analysis scripts into pure functions and writing a central_targets.Rconfiguration. In contrast,TempleCBErequires zero source code changes: you wrap existing project scripts, templates, raw data files, and outputs with a lightweight metadata manifest without touching a single line of existing analysis code. -
Language & format agnosticism: While
targetscan track external files viaformat = "file"or Quarto reports viatar_quarto(), it is primarily an R execution engine.TempleCBEtreats all files equally: a raw.xlsxfrom a clinical coordinator, a.sasdata step, a.pypreprocessing script, a.qmdQuarto document, and a rendered.pdfor.docxdeliverable are all first-class nodes. -
Domain-aware clinical semantics:
targetsnodes carry computational statuses (e.g.uptodate,queued,running).TempleCBEnodes carry domain-meaningful metadata: workflow lifecycle milestones (stage), semantic analytical roles (artifact_role: raw data, derived baseline data, imputed data, helper scripts, deliverable reports), modification timestamps (mtime), and plain-language descriptions. -
Decoupled execution vs. Monolithic runner:
targetstightly couples dependency analysis with execution viatar_make().TempleCBEdecouples staleness planning (get_render_plan()) from execution: it answers what is stale and in what topological order it must be rendered, leaving execution mechanics entirely up to the analyst (e.g. Quarto CLI, RStudio, GNU Make, or custom batch scripts). -
Multi-tier stakeholder communication: While
targetsprovides developer diagnostics (tar_visnetwork()),TempleCBEprovides rich, publication-ready and client-ready deliverables: zoomable HTML widgets with rich tooltips, neighborhood ego-subgraphs, custom Sugiyama-layout static PNGs, and collapsed stage-level diagrams.
Feature comparison matrix
| Dimension | targets |
TempleCBE::compute_graph |
|---|---|---|
| Primary purpose | Computation caching & pipeline execution engine | File dependency auditing, staleness planning & stakeholder visualization |
| Node representation | In-memory R objects / target expressions (cached in
_targets/) |
Explicit files on disk (FilePath,
FileUses, FileOutputs) |
| Invasiveness / barrier | High: requires refactoring code into pure R functions
in _targets.R
|
Low / Zero: non-intrusive metadata wrapper around existing files |
| Language support | R-centric (supports external files/tools via extensions) | Language- and format-agnostic (R, Quarto, Python, SAS, Excel, PDF) |
| Domain semantics | Computational status (hash, runtime, memory, skipped) | Clinical/study taxonomy (stage,
artifact_role, descriptions) |
| Staleness detection | AST code hashing & data content hashes | File-system modification timestamps
(mtime) |
| Execution model | Monolithic runner (tar_make()) handles
execution and storage |
Decoupled: get_render_plan() returns
topological order for custom execution |
| Relational analytics | Internal query tools (tar_network(),
tar_manifest()) |
Native bridge to igraph,
tidygraph::tbl_graph, and dplyr verbs |
| Stakeholder views | Developer-oriented target network | Zoomable HTML (visNetwork), PNG
(ggraph), stage collapse, ego subgraphs |
Specific gaps addressed by TempleCBE
In biostatistical consulting centers, academic medical centers, and
clinical research organizations, data science workflows face constraints
rarely accommodated by pure functional workflow engines.
TempleCBE was engineered to address five specific
operational gaps:
1. The “Retrofit & Legacy Pipeline” gap (Zero-rewrite adoption)
Most clinical and epidemiologic studies are already underway when
dependency tracking becomes urgent. Teams have dozens of pre-existing
Quarto/RMarkdown scripts, data cleaning scripts, and statistical models
written by different analysts over months or years. Rewriting an ongoing
multi-thousand-line project into pure R functions to satisfy
targets is often impossible due to locked regulatory
protocols, looming sponsor deadlines, or prohibitive refactoring costs.
TempleCBE can be layered over an existing project in under
an hour by declaring file relationships in a standalone manifest,
without modifying existing source code.
2. The “Heterogeneous Stack” gap (Multi-language clinical environments)
Real-world clinical pipelines rarely live entirely within R. A
typical study might ingest raw Excel spreadsheets from hospital clinical
research coordinators (CRCs), run legacy SAS macros for CDISC data
derivation, invoke Python for deep-learning image feature extraction,
render Quarto .qmd statistical reports, and produce
.pdf or .docx deliverables for Institutional
Review Boards (IRBs) and PIs. Because TempleCBE operates
strictly on file paths and modification times, it treats every component
across languages and software suites as a first-class citizen.
3. The “Semantic Data Lineage & Governance” gap
In regulated clinical trials and collaborative research, knowing that
a target is stale is not enough — auditors, biostatisticians, and
clinical monitors need to know what kind of asset it is and
where it sits in the data lifecycle. TempleCBE
formally tracks semantic roles:
-
raw_data: Immutable source data (e.g. initial registry export). -
derived_data: Standardized baseline dataset created from raw inputs. -
enhanced_data: Statistically augmented data (e.g. multiple imputation). -
intermediate_data: Stage-internal calculations or fitted model caches. -
report_source&deliverable_report: Executable documents and their deliverables. -
helper_script&reference: Child templates, macros, or lookup tables.
This taxonomy provides transparent data provenance and auditability out of the box.
4. The “Multilevel Stakeholder Communication” gap
An execution DAG with 200 granular function targets is invaluable to
the software developer, but overwhelming and unintelligible to a
clinical investigator, surgeon, or regulatory auditor.
TempleCBE bridges this communication divide through
multi-tiered visualization:
-
For analysts: Interactive
visNetworkHTML widgets with rich tooltips detailing file paths, modification dates, roles, and staleness warnings. -
For study sections: Focused ego-subgraphs
(
export_subgraph()) that isolate the neighborhood around a single deliverable or analytical stage. -
For protocol deliverables & manuscripts:
Sized-to-fit static figures (
print_pipeline()) with intelligent Sugiyama layout adjustments to prevent overlapping text labels. -
For executive sponsors: Stage-level collapsed
diagrams (
collapse_by_stage()) that condense a 90-file pipeline into a clear 4-node study milestone overview.
5. The “Decoupled Execution & Inspection” gap
Many institutional workflows prohibit autonomous pipeline runners
from executing scripts directly — whether due to strict HPC batch
submission policies, specialized Quarto rendering parameters,
interactive review requirements, or containerized runtimes.
TempleCBE isolates staleness detection from code execution:
get_render_plan() identifies out-of-date reports and
computes their topological render order, allowing the user, Makefile, or
CI/CD runner to trigger the execution using whatever environment or CLI
tools they prefer.
Building a small pipeline
The classes are:
| Class | Adds | Meaning |
|---|---|---|
FilePath |
— | Any file: name, path, stage, role, description |
FileUses |
dependencies |
A file that depends on upstream FilePath objects |
FileOutputs |
output |
A file (typically a rendering script) that also produces downstream files |
We build a tiny two-node pipeline out of files that ship with the
package itself: a helper .qmd and a report
.qmd that sources it. create_qmd_renderer() is
a convenience wrapper around FileOutputs() for the common
case of “this .qmd renders to a PDF of the same name.”
pipeline_config(
  study_name = "Example Pipeline",
  stage_labels = c(setup = "Setup", report = "Reporting"),
  stage_colors = list(setup = "#DDEBF7", report = "#D4EFDF")
)
#> $study_name
#> [1] "Example Pipeline"
#>
#> $stage_labels
#>       setup      report
#>     "Setup" "Reporting"
#>
#> $stage_colors
#> $stage_colors$setup
#> [1] "#DDEBF7"
#>
#> $stage_colors$report
#> [1] "#D4EFDF"
#>
#>
#> $default_formats
#> NULL

helper <- FilePath(
  name = "t_test_child",
  path = system.file("templates", "t_test_child.qmd", package = "TempleCBE"),
  renders = FALSE,
  stage = "setup",
  artifact_role = "helper_script"
)

report <- create_qmd_renderer(
  name = "t_test_example",
  path = system.file("templates", "t_test_example.qmd", package = "TempleCBE"),
  deps = list(helper),
  file_stage = "report",
  description = "Worked example of a one/two-sample t-test report"
)

pipeline <- list(helper, report)
report
#> S4 object of class: FileOutputs
#>   Name:        t_test_example
#>   Path:        /tmp/RtmppxIjyF/temp_libpath2188179f1d87/TempleCBE/templates/t_test_example.qmd
#>   Stage:       report
#>   Role:        report_source
#>   Renders:     TRUE
#>   Modified:    2026-10-29 19:14:52.993996
#>   Description: Worked example of a one/two-sample t-test report
#>   Dependencies:
#>     - t_test_child
#>   Outputs:
#>     - t_test_example PDF
Each FilePath object inspects the file on disk at
construction time, so mtime and file_ext are
already populated — that is what makes staleness detection possible
later.
Visualizing the graph
visualize_pipeline() returns a
DiagrammeR::grViz() object (or, with
extract_graph_code = TRUE, the raw DOT source) for a quick
interactive look, e.g. in the RStudio Viewer:
visualize_pipeline(pipeline)For a document deliverable, print_pipeline() lays the
same graph out with igraph/ggraph and saves it
as a sized-to-fit PNG:
png_path <- "pipeline_graph.png"
print_pipeline(pipeline, png_path)
knitr::include_graphics(png_path)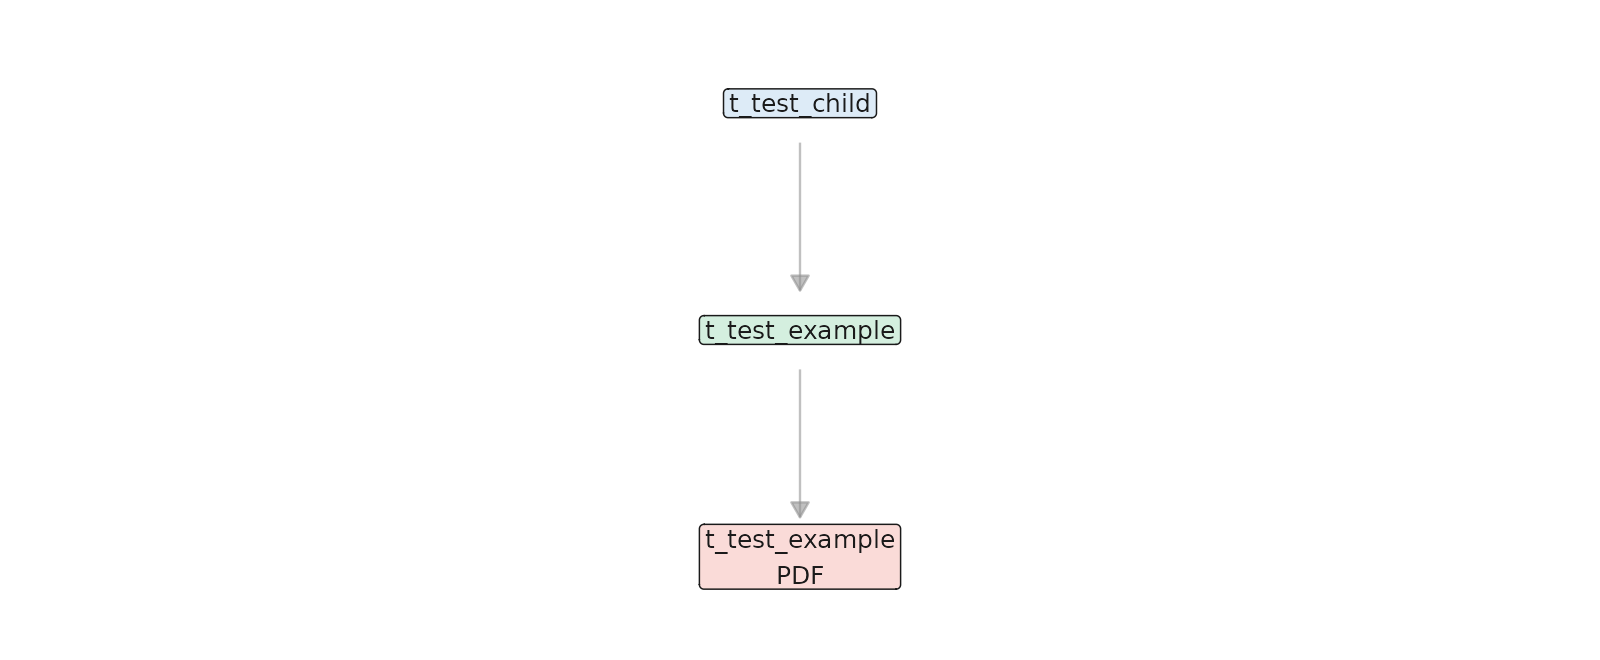
Staleness and render order
Because every node carries its own mtime,
get_render_plan() can compare each output’s modification
time against its sources and return only the reports that are actually
out of date — topologically sorted, so upstream reports always come
before the downstream reports that depend on them:
plan <- get_render_plan(pipeline)
names(plan)
#> [1] "t_test_example"
pipeline_summary() gives the same information as an
at-a-glance table — node/edge counts, staleness, and a stage-by-role
breakdown — useful as a standing status check without re-deriving the
graph by hand:
pipeline_summary(pipeline)
#> ========================================================================
#>                       Computational Pipeline Summary
#> ========================================================================
#> Total Nodes: 3 | Total Edges: 2 | Stale Nodes: 1 (Needs Re-render)
#>
#> Artifact Roles:
#>   - deliverable_report        :  1
#>   - helper_script             :  1
#>   - report_source             :  1
#>
#> Pipeline Stages Breakdown:
#>   stage Reports Data_Files Helpers Total
#>  report       2          0       0     2
#>   setup       0          0       1     1
#> ========================================================================
Interoperating with tidygraph
as_pipeline_graph() converts the object list to a
tidygraph::tbl_graph, which brings ordinary dplyr verbs to
the graph’s node and edge tables:
library(tidygraph)
library(dplyr)

as_pipeline_graph(pipeline) |>
  activate(nodes) |>
  as_tibble() |>
  select(name, stage, artifact_role, renders)
#> # A tibble: 3 × 4
#>   name               stage  artifact_role      renders
#>   <chr>              <chr>  <chr>              <lgl>
#> 1 t_test_child       setup  helper_script      FALSE
#> 2 t_test_example     report report_source      TRUE
#> 3 t_test_example PDF report deliverable_report FALSE
Comparing two pipeline snapshots
as_pipeline_graph()/as_igraph() answer
“what does the pipeline look like.” A different, equally common question
is “what changed” — between a MakeComputeGraph.R run today
and one from last week, or between two analysts’ working copies of the
same study. as_database(), graph_intersect(),
graph_subtract(), and graph_union() (see
?database_setops) answer that directly, working on any
graph object — an igraph, a tbl_graph, or the
igraph this package’s own as_igraph()
produces.
Suppose report’s description gets finalized after an
earlier draft:
report_yesterday <- create_qmd_renderer(
  name = "t_test_example",
  path = system.file("templates", "t_test_example.qmd", package = "TempleCBE"),
  deps = list(helper),
  file_stage = "report",
  description = "Draft t-test report (not yet finalized)"
)

pipeline_yesterday <- list(helper, report_yesterday)

g_today <- as_igraph(pipeline)
g_yesterday <- as_igraph(pipeline_yesterday)
Both snapshots share every node (same file paths, same names), so
graph_intersect() keeps all of them — but whose
description comes through?
as_database(graph_intersect(g_today, g_yesterday))$nodes |>
  select(name, description)
#> # A tibble: 3 × 2
#>   name               description
#>   <chr>              <chr>
#> 1 t_test_child       ""
#> 2 t_test_example     "Worked example of a one/two-sample t-test report"
#> 3 t_test_example PDF ""
Today’s description survives; yesterday’s is silently discarded.
That’s not a bug to work around — it’s the documented contract of
dplyr::intersect()/ dplyr::setdiff() on a
cbe_database (see ?database_setops): attribute
values always come from the first graph argument, never merged with the
second. For a pipeline graph, whose nodes carry exactly this kind of
node-specific metadata (stage, mtime,
description), that choice determines what you see when you
compare snapshots, so pass the more recent one first.
graph_subtract() answers “what’s new since
yesterday”:
as_database(graph_subtract(g_today, g_yesterday))$nodes
#> # A tibble: 0 × 12
#> # ℹ 12 variables: name <chr>, label <chr>, stage <chr>, artifact_role <chr>,
#> #   color <chr>, stale <lgl>, path <chr>, description <chr>, renders <lgl>,
#> #   shape <chr>, mtime <chr>, title <chr>
Nothing here, since today and yesterday have identical node sets in
this toy example — a real MakeComputeGraph.R diff would
surface any newly added FilePath/FileOutputs
nodes instead.
graph_union() is the odd one out: rather than taking
attribute values from one side only, it coalesces them,
so neither snapshot’s data is silently dropped on overlap:
as_database(graph_union(g_today, g_yesterday))$nodes |>
  select(name, description)
#> # A tibble: 3 × 2
#>   name               description
#>   <chr>              <chr>
#> 1 t_test_child       ""
#> 2 t_test_example     "Worked example of a one/two-sample t-test report"
#> 3 t_test_example PDF ""
This is the same union-and-coalesce behavior as
join_pipelines() (Pattern 5, above) —
join_pipelines() is tbl_graph-specific and
keys on name, while graph_union() works on any
graph type via as_database() and lets you choose the join
key with node_by. Reach for
join_pipelines()/graph_union() to build one
combined graph out of complementary, non-conflicting pieces, and for
graph_intersect()/ graph_subtract() to compare
two versions of the same pipeline over time, where you
specifically want one side’s values to win rather than merge.
Sharing an interactive version
For a collaborator who wants to pan, zoom, and hover over individual
nodes rather than read a static image,
export_interactive_pipeline() writes a self-contained HTML
file (via visNetwork/htmlwidgets) with the
same staleness coloring and per-node tooltips:
export_interactive_pipeline(pipeline, file = "pipeline.html")For pipelines large enough that the full per-file graph stops being
legible as one image, collapse_by_stage() reduces it to one
node per stage first:
full_graph <- as_igraph(pipeline)
collapsed <- collapse_by_stage(full_graph)
igraph::vcount(full_graph)
#> [1] 3
igraph::vcount(collapsed)
#> [1] 2
How others can use this technology
The TempleCBE compute graph is intentionally modular and
can be integrated into any data science or biostatistical workflow. Here
are five concrete patterns for adopting this technology in your own
projects:
Pattern 1: Project-level orchestration with
MakeComputeGraph.R (study-level pattern)
In production biostatistical pipelines and collaborative studies
(modeled after the architecture used across CBE studies and
TempleCBE), best practice is to encapsulate the entire
project dependency structure in a centralized orchestration script named
MakeComputeGraph.R.
Rather than hardcoding ad-hoc graphs in interactive sessions,
MakeComputeGraph.R provides a single source of truth for
the entire study lifecycle:
-
Configures study stages & visual identity: Uses
pipeline_config()to establish human-readable labels and color coding for every analytical phase. -
Declares raw & derived assets: Uses
FilePath()with semantic roles (raw_data,derived_data) so analysts know which files are source registries vs. derived caches. -
Connects executable reports & vignettes: Uses
create_qmd_renderer()to link reports to their explicit data dependencies and to each other in topological order.
TempleCBE ships with this exact architecture in
vignettes/MakeComputeGraph.R (and
inst/scripts/MakeComputeGraph.R), orchestrating all four
analytical vignettes:
library(TempleCBE)
library(dplyr)

make_temple_compute_graph <- function() {
  # 1. Project Pipeline Configuration
  pipeline_config(
    study_name = "TempleCBE Biostatistical & Survival Analysis Architecture",
    stage_labels = c(
      "01_EDA"            = "Exploratory Data Analysis & Quality Audit",
      "02_Survival_CV"    = "Penalized Coxnet & Nested Cross-Validation",
      "03_Compute_Graph"  = "Pipeline Dependency & Governance Graph",
      "04_SAS_Validation" = "SAS PROC PHREG Benchmark Validation"
    ),
    stage_colors = list(
      "01_EDA"            = "#DDEBF7",
      "02_Survival_CV"    = "#FCE4D6",
      "03_Compute_Graph"  = "#E8DAEF",
      "04_SAS_Validation" = "#D4EFDF"
    )
  )

  # 2. Raw Data Inputs
  raw_clinical <- FilePath(
    name = "raw_patient_registry",
    path = "data/raw/patient_registry.csv",
    renders = FALSE,
    stage = "01_EDA",
    artifact_role = "raw_data",
    description = "Raw clinical intake data with missing biomarker measurements"
  )

  sas_benchmark_raw <- FilePath(
    name = "tumor_wide_data",
    path = "data/raw/Tumor.xlsx",
    renders = FALSE,
    stage = "04_SAS_Validation",
    artifact_role = "raw_data",
    description = "45-animal longitudinal papilloma count study (SAS Example 85.7)"
  )

  # 3. Stage 01: EDA & Missingness Analysis
  cleaned_cohort_rds <- FilePath(
    name = "cleaned_cohort_rds",
    path = "data/derived/cleaned_cohort.rds",
    renders = FALSE,
    stage = "01_EDA",
    artifact_role = "derived_data",
    description = "Audited and normalized clinical cohort"
  )

  eda_report <- create_qmd_renderer(
    name = "01_eda_and_missingness",
    path = "vignettes/eda_and_missingness.Rmd",
    deps = list(raw_clinical),
    file_stage = "01_EDA",
    description = "Missingness auditing, outlier fences, and feature normalization"
  )
  eda_report@output <- c(eda_report@output, list(cleaned_cohort_rds))

  # 4. Stage 02: Penalized Coxnet & Nested Cross-Validation
  survival_cv_report <- create_qmd_renderer(
    name = "02_nested_survival_cv",
    path = "vignettes/nested_survival_cv.Rmd",
    deps = list(cleaned_cohort_rds),
    file_stage = "02_Survival_CV",
    description = "Subject-grouped nested cross-validation and elastic-net Cox modeling"
  )

  # 5. Stage 04: SAS Validation & Time-Dependent Covariates
  tumor_cp_rds <- FilePath(
    name = "tumor_counting_process_rds",
    path = "data/derived/Tumor1.rds",
    renders = FALSE,
    stage = "04_SAS_Validation",
    artifact_role = "derived_data",
    description = "Start/stop counting-process records generated via tidy_tmerge_cox"
  )

  sas_report <- create_qmd_renderer(
    name = "04_sas_survival",
    path = "vignettes/sas_survival.Rmd",
    deps = list(sas_benchmark_raw),
    file_stage = "04_SAS_Validation",
    description = "Numerical validation against SAS PROC PHREG and tidy start/stop merging"
  )
  sas_report@output <- c(sas_report@output, list(tumor_cp_rds))

  # 6. Stage 03: Compute Graph & Governance
  graph_report <- create_qmd_renderer(
    name = "03_compute_graph",
    path = "vignettes/compute_graph.Rmd",
    deps = list(eda_report, survival_cv_report, sas_report),
    file_stage = "03_Compute_Graph",
    description = "Dependency graph auditing, staleness detection, and pipeline governance"
  )

  # Assemble full pipeline
  list(
    raw_clinical,
    sas_benchmark_raw,
    eda_report,
    cleaned_cohort_rds,
    survival_cv_report,
    sas_report,
    tumor_cp_rds,
    graph_report
  )
}
When this script is run, calling pipeline_summary() on
the resulting pipeline immediately yields a structured governance audit
across all project stages:
mcg_path <- if (file.exists("MakeComputeGraph.R")) {
  "MakeComputeGraph.R"
} else if (file.exists("vignettes/MakeComputeGraph.R")) {
  "vignettes/MakeComputeGraph.R"
} else {
  system.file("scripts", "MakeComputeGraph.R", package = "TempleCBE")
}

if (nzchar(mcg_path) && file.exists(mcg_path)) {
  source(mcg_path)
  temple_pipe <- make_temple_compute_graph()
  pipeline_summary(temple_pipe)
}
#> ========================================================================
#>                       Computational Pipeline Summary
#> ========================================================================
#> Total Nodes: 12 | Total Edges: 12 | Stale Nodes: 6 (Needs Re-render)
#>
#> Artifact Roles:
#>   - deliverable_report        :  4
#>   - derived_data              :  2
#>   - raw_data                  :  2
#>   - report_source             :  4
#>
#> Pipeline Stages Breakdown:
#>              stage Reports Data_Files Helpers Total
#>             01_EDA       2          2       0     4
#>     02_Survival_CV       2          0       0     2
#>   03_Compute_Graph       2          0       0     2
#>  04_SAS_Validation       2          2       0     4
#> ========================================================================
You can also use list_stage_data_artifacts() to scan
directories and catalogue derived data files automatically:
# Inspect all data files in an imputation output folder
stage_artifacts <- list_stage_data_artifacts(
  stage_dir = "data/derived/imputation",
  stage = "03_imputation"
)
Pattern 2: Delivering interactive DAGs to clinical collaborators
Non-technical investigators and sponsors frequently want to know where a specific number or figure in a final report came from. You can export a self-contained HTML file with rich interactive cards and search bars:
# Export full interactive HTML for stakeholder distribution
export_interactive_pipeline(
  study_pipeline,
  file = "deliverables/pipeline_lineage.html",
  title = "Study Data Lineage & Report Dependencies"
)

# Or export an ego-subgraph isolating a single report and its direct inputs
export_subgraph(
  study_pipeline,
  focal_node = "02_eda_report",
  order = 1,
  file = "deliverables/eda_subgraph.html"
)
Pattern 3: Automated staleness-driven re-rendering
Instead of manually checking whether data files have changed or
re-rendering all reports from scratch, use
get_render_plan() to drive selective rendering in a build
script or CI/CD workflow:
# Detect out-of-date reports in topological dependency order
render_plan <- get_render_plan(study_pipeline)

if (length(render_plan) > 0) {
  for (report_obj in render_plan) {
    message("Rendering out-of-date report: ", report_obj@path)
    quarto::quarto_render(input = report_obj@path)
  }
} else {
  message("All reports are up-to-date with their underlying data.")
}
Pattern 4: Relational pipeline governance with
tidygraph and dplyr
Because as_pipeline_graph() converts the pipeline
directly to a tidygraph::tbl_graph, you can audit and query
your workflow using standard tidyverse grammar:
library(tidygraph)
library(dplyr)

tg <- as_pipeline_graph(study_pipeline)

# List all reports that depend on a specific raw data file
upstream_data <- "patient_registry_xlsx"
downstream_reports <- tg |>
  activate(nodes) |>
  mutate(dist = node_distance_from(which(name == upstream_data), mode = "out")) |>
  filter(is.finite(dist), artifact_role == "deliverable_report") |>
  as_tibble()

# Audit unrendered or orphaned scripts across stages
orphans <- tg |>
  activate(nodes) |>
  filter(node_is_isolated()) |>
  as_tibble()
Pattern 5: Multi-analyst pipeline composition
In large studies where different biostatisticians manage different
domains (e.g. one analyst leads clinical safety, another leads genomics,
and a third leads pharmacokinetics), each analyst can maintain their own
sub-pipeline. Use join_pipelines() to combine them into an
overarching study graph without duplicating shared nodes:
# Merge clinical and genomics pipelines
full_study_graph <- join_pipelines(clinical_subpipeline, genomics_subpipeline)

# Generate executive summary of combined study
pipeline_summary(full_study_graph)
Choosing between targets and TempleCBE (or
combining both)
targets and TempleCBE solve fundamentally
different problems and can be chosen based on project needs:
When to choose targets
- Your project is written predominantly in R functions.
- You have compute-intensive steps (e.g. fitting 50,000 MCMC models, large bootstrap resamples, complex machine learning cross-validation) where function-level caching saves hours of runtime.
- You need distributed computation across a high-performance computing
cluster (SLURM, SGE, AWS) via
crew.
When to choose TempleCBE
- You are working in an existing project with established scripts and reports that cannot be refactored into pure functions.
- Your project spans multiple languages and tools (Excel, SAS, Python, Quarto, R).
- You need explicit clinical governance, tracking artifact roles
(
raw_data,enhanced_data,deliverable_report) and data provenance. - You need to communicate the pipeline to clinical investigators, clients, or regulatory bodies via interactive HTML widgets or publication-quality figures.
- You want decoupled staleness detection without ceding execution control to an autonomous framework.
Combining both in a hybrid architecture
targets and TempleCBE are not mutually
exclusive. A common, highly effective pattern in clinical data science
is a two-layer hybrid architecture:
-
Low-level compute layer (
targets): Heavy statistical simulation, model tuning, or imputation calculations are managed bytargetsinside ananalysis/models/subfolder, writing final analytical datasets or tables to disk (e.g.data/imputed_data.rds). -
High-level governance layer
(
TempleCBE):TempleCBEtracks the overall study graph from raw intake data, through thetargets-generated artifacts, to the final Quarto reports and deliverable PDFs, providing executive summaries, staleness planning, and stakeholder visualizations.